Most TM1 users will never have to worry about how the engine works. They open a view, change an assumption, and expect the result to appear. That is exactly how a planning system should feel.
But TM1’s ability to incorporate very large datasets into interactive planning models is not accidental. And when performance problems do appear, it is worth looking under the hood. In many cases, the problem is not that the model contains “too much data.” It is that storage, dimension order, rules, feeders, or queries have made the engine do more work than the business question requires. Those problems can often be solved because they are problems of model selectivity, not an unavoidable limit of the technology.
TM1 was fast decades ago and is still fast today for the same fundamental reason: it does not treat every possible cell in a multidimensional model as something that must be stored and calculated in advance.
Its architecture concentrates work on what is populated, what is requested, and what is affected by a change. In-memory execution makes that work fast. Selectivity keeps the amount of work under control.
TM1 Was Fast Before “In Memory” Became a Category
TM1’s speed is often reduced to one phrase: it is an in-memory database. That is true, but incomplete.
Manny Perez has described the first system as an answer to an interactive planning problem at Exxon. Planners needed to change assumptions and see consolidations quickly enough to continue thinking. Disk-oriented queries and long recalculation cycles would have broken that interaction. In Cubewise’s public 2019 interview with Manny Perez, the origin of the in-memory functional database is tied directly to that planning requirement.
Yet memory alone cannot explain TM1’s longevity. Put a dense multidimensional array in RAM, calculate every possible consolidation, and it will still exhaust the available machine. Faster hardware postpones the problem; it does not remove it.
TM1 was designed around a more durable idea: the theoretical model can be enormous while the physical workload remains selective.
That distinction mattered on the constrained machines of the 1980s and 1990s. It still matters on modern servers because business models have expanded with the hardware. More products, customers, employees, projects, scenarios, versions, measures, and time periods create a logical space that can grow far faster than the amount of meaningful data inside it.
The Largest Part of a Cube Usually Contains Nothing
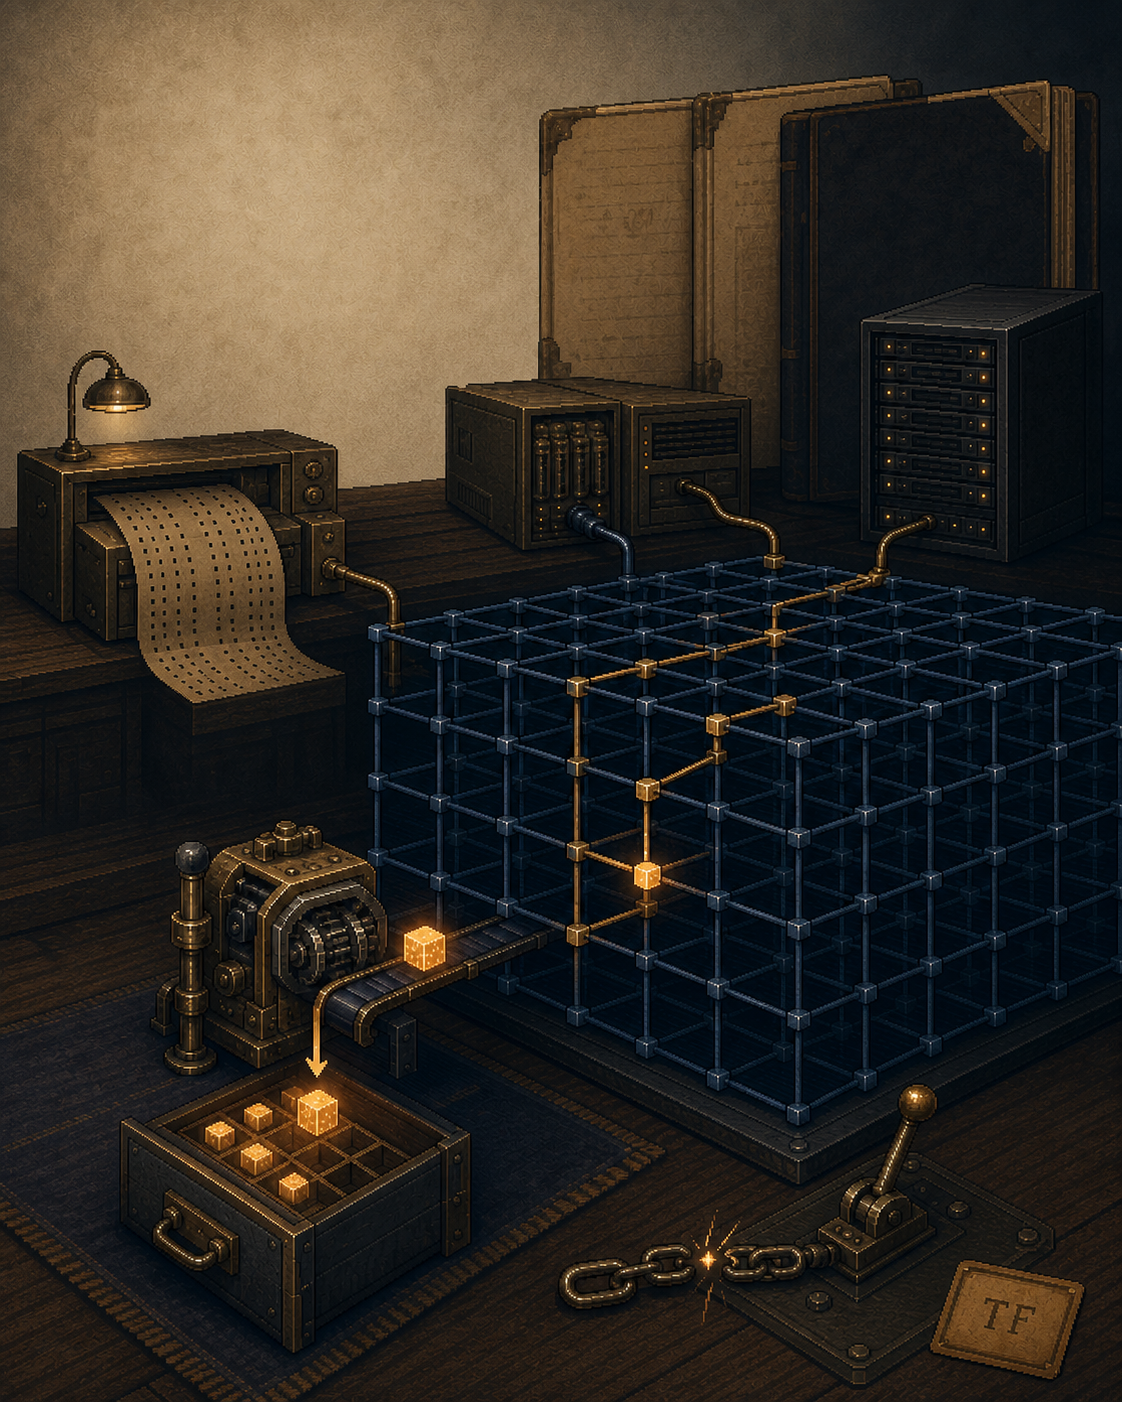
The theoretical size of a cube is the product of its dimensions. A model containing products, customers, locations, entities, scenarios, versions, measures, and periods can define trillions of possible coordinates.
Most of those coordinates may have no business meaning. No sale occurred for that product, customer, and month. No forecast was entered for that entity and scenario. No employee belongs to that cost centre in that version. These combinations are possible addresses, not necessarily stored zeroes.
Doug Kimelman and Manny Perez formalized this distinction in the IBM Research report A Functional Data Model for Analytics, published as RC25412 in 2013. The report describes real business cubes with densities below one populated cell in ten billion possible cells as not atypical.
At that density, allocating the whole Cartesian product would be absurd. The practical problem is smaller:
populated base cells
+ paths and indexes needed to find them
+ relevant rule and consolidation dependencies
+ useful cached results
+ feeder and structural overhead
These components can still become large. The crucial point is that they do not have to grow in direct proportion to every possible coordinate.
TM1 Does Not Store Empty Possibility
The first part of TM1’s speed is sparse storage.
Manny Perez’s US Patent 5,592,666, filed in 1994, addressed the memory wasted when a multidimensional structure reserves pointer space for elements that do not contain data. The patent describes allocating storage around values that exist, using presence indicators and subsidiary hierarchical indexes to avoid representing the entire dimensional space cell by cell.
A patent is not a release history. It does not prove that every described mechanism appeared unchanged in a particular version of TM1. It does establish the design problem and the proposed architectural answer: storage should follow populated values rather than the full theoretical cube.
Perez later recalled that TM1’s sparse storage evolved from nested pointer vectors toward compressed trie structures as dimensions and models grew. The implementation changed, but the governing principle remained stable. Empty combinations could remain available as addresses without occupying the memory of fully allocated cells.
This is why the phrase “large cube” can be misleading. A cube may be logically vast and physically manageable. What matters is not only how many possible cells exist, but how many paths the engine must maintain to populated or otherwise relevant intersections.
Dimension Order Determines the Cost of Those Paths
Sparse storage does not make model organization irrelevant.
Hubert Heijkers’s public Cubewise session How TM1 Really Works explains mature TM1 as a sparse multidimensional calculation engine and identifies dimension order as a determinant of memory footprint and performance. Two cubes can contain the same dimensions and the same populated values yet require different amounts of memory and traversal work when those dimensions are ordered differently.
Changing the order changes the branching pattern of the internal structures that lead to populated and fed cells. One order may let many intersections share parts of a path. Another may create wider or more fragmented branches.
There is no universal ordering formula that works for every model. The favorable order depends on cardinality, data distribution, and access pattern. The important point is that dimension order is not cosmetic. It influences how efficiently TM1 turns a sparse logical model into a physical in-memory structure.
This is also why a slow cube is not necessarily an oversized cube. Sometimes the model contains a reasonable quantity of data arranged in a physically expensive way.
TM1 Does Not Calculate Every Possible Answer
Sparse storage solves only half the problem. An OLAP engine could store leaf data efficiently and then recreate the explosion by precalculating every possible consolidation and rule-derived value.
Perez’s earlier US Patent 5,319,777, filed in 1990, described calculated values that remain undefined until requested. Once calculated, a result can be retained. When an underlying dependency changes, the affected result becomes invalid and must be calculated again.
This is calculation on demand. TM1 starts with the cell the user has requested and resolves what that cell needs. A requested value may be stored directly, consolidated from descendants, or calculated by a rule. Its dependencies may require further cells. The engine follows that chain until it can return the answer.
The 2013 IBM report explains why global precalculation becomes untenable. Hierarchies create geometrically many possible consolidations. Rules can create dependencies across cells and cubes. Users, however, normally ask for small slices of that total space.
TM1 therefore does not require every possible answer to exist before useful work begins. It calculates the answers users actually request.
That does not mean TM1 performs no work in advance. It prepares structures, processes feeders, and retains calculated or consolidated results. The distinction is between selective preparation and blanket permanent materialization.
Caching Prevents Selectivity From Becoming Repetition
Calculation on demand would be inefficient if the engine rebuilt the same expensive answer from the leaves every time.
TM1 therefore sits between two extremes:
- calculate and store every possible result in advance;
- recalculate every requested result from the beginning every time.
Useful results can be cached and reused while they remain valid. When data changes, affected caches are invalidated. Perez’s 1990-filed patent documents the basic calculate, retain, and invalidate cycle. The IBM functional-model report treats caching and dependency invalidation as necessary parts of an interactive functional database. Perez later named Stargate among TM1’s major performance developments.
The model invests calculation effort in the areas users actually visit. Repeated, stable requests can benefit from reused results. Writeback invalidates what has changed without requiring the system to rebuild every possible view.
This also explains why query behavior matters. A workload that repeatedly asks related questions may benefit greatly from caching. A workload that constantly jumps to unrelated areas or invalidates large dependency networks will reuse less work.
Feeders Tell the Sparse Engine Which Empty Cells Matter
Rules create a special problem for sparse calculation. A coordinate with no stored input can still return a calculated value. If consolidation follows only stored cells, it may never discover that contribution.
Feeders provide the missing knowledge. Heijkers’s presentation makes the distinction between feeder statements and the stored feeder markers created when those statements are processed. The statement describes the dependency. The marker tells sparse consolidation that an apparently empty rule-derived cell must be visited.
Feeders are therefore not an unrelated technical oddity. They are part of the same architecture that makes TM1 fast: ignore irrelevant empty space while identifying the exceptions that can contribute a result.
The trade-off is exact. Underfeeding is a correctness problem because valid contributions can disappear from consolidations. Overfeeding is a memory and performance problem because unnecessary markers make a larger part of the logical cube operationally relevant.
A model may consequently be almost empty on paper and behave like a much denser model in practice. The problem is not the number of stored values alone. It is the combination of stored values, rules, feeder markers, and the paths required to reach them.
Multiple Cubes Keep Irrelevant Dimensions Apart
Applix’s iTM1 technology pages around 2000 presented multiple compact cubes as another defense against data explosion. The pages were vendor material, so their quantitative claims require caution. The underlying modeling principle remains important.
Not every measure varies across every business dimension. Workforce planning may need employee and position detail that sales planning does not. Currency rates need currency and period but not customer or product. A universal cube forces unrelated processes into a single combinatorial space.
Multiple cubes reduce the problem before sparse storage and calculation on demand have to solve it. Each subject area can carry the dimensions it actually needs, while explicit processes and rules connect the models where necessary.
This design can also be abused. Broad cross-cube rules can recreate the same complexity through dependencies. But the architectural purpose is clear: do not make the engine navigate combinations the business problem never required.
What to Examine When TM1 Becomes Slow
TM1’s architecture does not make every model automatically fast. It makes performance problems more explainable.
When a long-running model slows down, the useful question is often not “Have we exceeded TM1’s data limit?” but “What has made this workload less selective?”
The answer may lie in several places:
- a cube contains dimensions that do not belong to the same business problem;
- dimension order creates expensive branching for the actual data distribution;
- rules define dependencies across unnecessarily broad areas;
- overfeeding stores markers for large regions that never contribute useful results;
- user queries repeatedly request wide or unrelated areas;
- frequent changes invalidate large caches before they can be reused;
- dense transaction history has been placed in a workload better suited to relational or columnar scanning.
These are not all simple fixes, and not every workload belongs in TM1. But they are inspectable design choices. That is the practical value of understanding the engine. Performance problems often reveal that the model has stopped preserving the selectivity on which TM1’s speed depends.
Why TM1 Is Still Fast
Modern hardware is vastly more powerful than the machines on which TM1 first ran. Modern planning models are also vastly larger and more connected. The persistence of TM1’s performance is therefore not just a story of faster processors and more memory.
The architecture continues to avoid unnecessary work:
sparse indexing
    + efficient dimensional structure
    + calculation on demand
    + dependency-aware caching and invalidation
    + feeders for rule-derived exceptions
    + relevant multi-cube design
    + in-memory access
TM1 remains strongest when much meaningful multidimensional data sits inside a logical space larger by many orders of magnitude, and when users need to write, recalculate, and continue working without waiting for the entire model to be rebuilt.
Its advantage weakens in dense cubes, scan-oriented transaction histories, indiscriminate rule networks, overfed models, poor dimension orders, and workloads that continually defeat cache reuse. That is not a contradiction of the architecture. It defines the conditions under which the architecture works.
TM1 was fast decades ago and is still fast for one coherent reason: it makes the relevant part of the model—not the full universe of empty possibility—the practical unit of storage and calculation.
Most users never need to know that. When performance deteriorates, understanding it can make the difference between assuming the platform has reached its limit and discovering that the model can be made selective again.